
The Finance AI Agent Risks Most Teams Miss Before They Build

If you are evaluating AI agents for finance, whether they run on OpenAI, Claude, or anything else, three risks tend to show up after go-live rather than before: your data leaving your infrastructure, hallucinated journal entries, and no audit trail on the API calls. Here is what each one looks like in practice, and what to check before you build.
- The model is the easy part. The risk lives in what happens around it: where your data goes, whether the numbers are real, and whether every action is recorded.
- Data leaving your infrastructure is the first exposure. Financials sent to a third-party model to get an answer have crossed a boundary you cannot pull them back across.
- A hallucinated journal entry is not a typo. In financial reporting it is a material weakness, and a model that generates numbers will invent one confidently.
- No audit trail on API calls means that when an auditor asks who ran what and what a human approved, "the API did it" is the only answer you have.
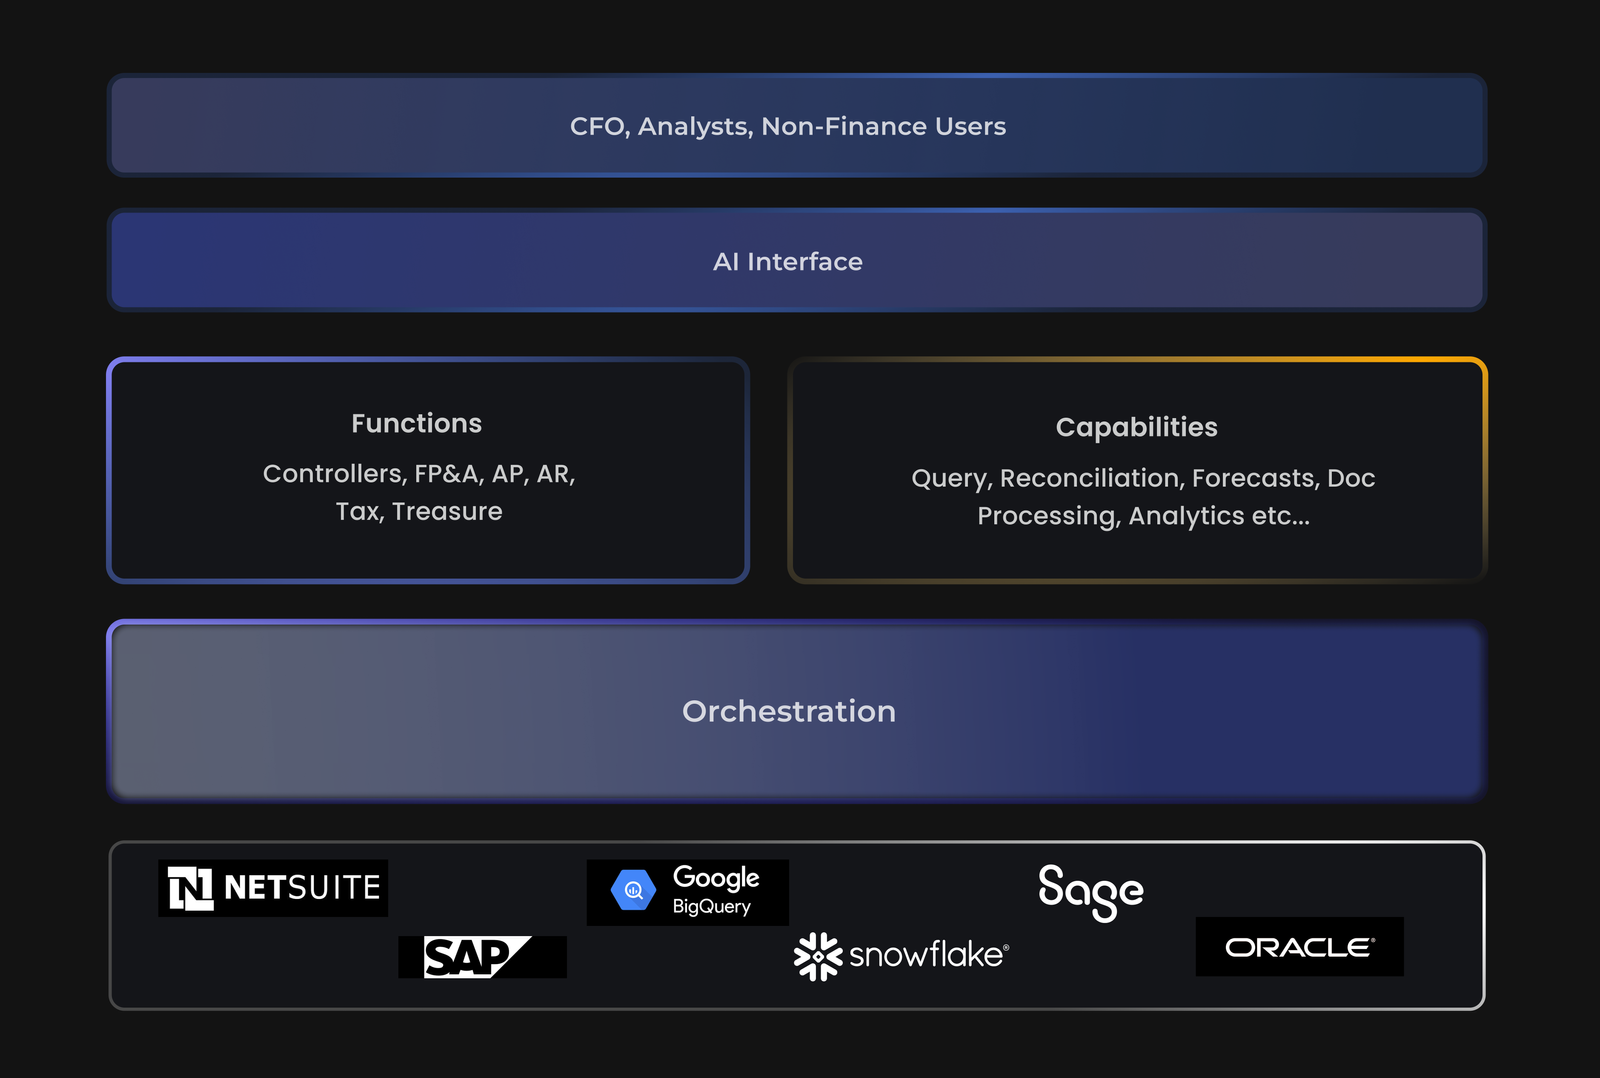
- ChatFin runs as a governed, model-agnostic layer above the model: output grounded in your ERP, entries drafted not posted, and every action logged.
Picking the model is the part every team gets right. OpenAI or Claude, frontier or mid-tier, the reasoning is good enough for finance work today. The mistake is treating the model as the product. In finance, the model is one component inside a system that has to move data safely, produce numbers that are real, and record what it did well enough to survive an audit.
Those three requirements are exactly where a raw model agent is weakest, and they rarely surface in a demo. They surface a quarter later, in a controls review or a restated number, when they are expensive to fix. The three risks below are the ones we see teams miss most often, and none of them is a reason to avoid AI. Each is a reason to put the right layer between the model and the ledger.
All three are invisible when the agent is answering questions in a sandbox. They only bite once the agent touches real data, posts to a real ledger, or lands in front of a real auditor. By then the architecture is set, so the cheapest time to ask about them is before the first line of the build.
Risk 1: Your data leaves your infrastructure
To answer a finance question, a raw model agent has to send the context to the model. That means account balances, vendor names, contract terms, and payroll figures travel to a third-party endpoint to get an answer back. Sometimes that is contractually fine and sometimes it is not, but most teams never map exactly what leaves, where it lands, or how long it is retained. The quieter version of the same risk is staff pasting a GL extract into a public chatbot to save an hour, with no record that it happened.
Data you sent to a third-party model to answer one question is data you can no longer promise stayed inside your controls.
What good looks like is simple to state and harder to build. The agent should read your financial data through a governed connection, not a copy paste. That data should be encrypted in transit and at rest, held in a tenant that is not shared with anyone else, and kept in a region you chose. And you should be able to see the connector code rather than trust a description of it. ChatFin reads and writes through your ERP's native APIs, keeps each customer in an isolated tenant with data residency in the US and EU, encrypts with AES-256 at rest and TLS 1.3 in transit, and ships its ERP connectors as open source so your security team can audit them directly.
Risk 2: Hallucinated journal entries
A language model is built to produce a plausible answer, not a correct one. Ask it for a balance and it will give you a number that reads exactly like the right number, whether or not that figure exists in your ledger. In a chat window that is a nuisance. In the general ledger it is a misstatement, and a hallucinated entry that reaches your books is treated by an auditor as a material weakness, not a slip.
The fix is to stop letting the model produce the number at all. A well-built finance agent uses the model only to understand what you asked, then runs deterministic code against your verified data to get the figure. Ask ChatFin to calculate revenue by region and it does not guess. It generates a query against your ERP data and returns what the query returns, so the number is retrieved rather than invented. Entries are drafted, not posted, and every draft carries the evidence behind it. A controller reviews the logic and approves before anything reaches the ledger, which means a wrong proposal is caught at the review step instead of in next quarter's restatement.

Risk 3: No audit trail on the API calls
An agent wired to your systems through an API can read and write all day, but the API call itself is not an audit trail. When the auditor asks who initiated an action, what data it read, which rule it applied, and which person approved it, a stack of API logs does not answer the question. Most teams that build on raw model endpoints discover this gap only when they are asked to prove a number, and by then the events they need were never recorded in a usable form.
A finance-grade agent records every action as it happens: who ran it, what changed, what was approved, and the exact query behind the figure, in a log an auditor can read and even re-run independently. ChatFin captures both the agent's proposal and the human's authorization on every write-back, which is what Internal Control over Financial Reporting expects. It also versions your financial logic, so if the definition of a metric changes, the record shows who changed it, when, and why, and a historical report can be rebuilt on the logic that was live at the time. Beyond individual entries, the same layer can watch for unusual patterns such as entries posted at odd hours or access outside a user's normal scope.

Three more worth naming
The three above are the ones the email flagged, but a technical reviewer will raise a few more in the same breath. They are worth a line each.
A short checklist before you build
Six questions separate an agent that demos well from one that holds up in production. Ask them of anything you build or buy, including us.
How ChatFin handles the three
ChatFin is a governed layer that sits between the model and your ledger, rather than a wrapper around one model. It uses the language model to understand intent and deterministic code to execute, so the reasoning is flexible but the numbers come from your data. It reads and writes through your ERP's native APIs, keeps entries as drafts until a controller approves, and records every action with its evidence. Because the layer is built for finance rather than general chat, the controls are part of the design, not an add-on.
| Concern | Raw model agent | Governed finance layer |
|---|---|---|
| Your data | Sent to a third-party model to answer | Read through your ERP API, held in an isolated tenant and region |
| The numbers | Generated by the model, can be invented | Retrieved by a query you can re-run |
| Write-back | Can post directly if wired to | Drafted, never posted without human approval |
| Audit trail | API logs, if you built them | Every action logged: who, what changed, what approved |
| Access | Broad service account | Mirrors the user's existing ERP permissions |
| The model | Hard-wired to one vendor | Swappable, the layer is model-agnostic |
The security posture behind it is stated plainly: AES-256 at rest, TLS 1.3 in transit, SOC 2 Type II, isolated tenants, data residency in the US and EU, and open-source connectors. None of that removes the human. It puts the human where the risk is, at the approval step, and keeps the record of everything on either side of it.

Frequently Asked Questions
Does this mean we should not use OpenAI or Claude for finance?
No. Use them. The point is to run them through a layer that keeps your data in your controls, retrieves numbers instead of generating them, requires human approval to post, and logs every action. The model is fine; the wrapper around it is where the risk is.
What exactly is a hallucinated journal entry?
It is an entry whose amount, account, or rationale the model produced from its own output rather than from your ledger. It can look completely reasonable, which is why it is dangerous. Grounding the agent in your ERP data and keeping entries as drafts for human approval is what stops one from reaching the books.
If we build on raw model APIs ourselves, can we still get an audit trail?
Yes, but you have to build and maintain the logging, the grounding, the approval workflow, and the access controls yourself, and keep them aligned as the ERP and the model change. Most teams underestimate that work, which is the gap a purpose-built finance layer closes.
Is ChatFin tied to one AI model?
No. ChatFin is model-agnostic. The governance, grounding, and audit trail sit in the layer, so the underlying model can change without rebuilding the workflow that depends on it.
Build on the model, govern the layer
The three risks that catch finance teams, data leaving your infrastructure, hallucinated journal entries, and no audit trail on API calls, are not arguments against AI agents. They are the checklist for building one that survives an audit and a bad Monday. Ground the output in your own data, keep entries as drafts a person signs, and record everything on both sides of the approval.
ChatFin runs as that governed, model-agnostic layer on top of the ERP you already use, so you get the speed of an AI agent without giving up the controls finance is measured on.